CATEGORY
Mapping artifact risk to the frameworks your auditors and your board already know.
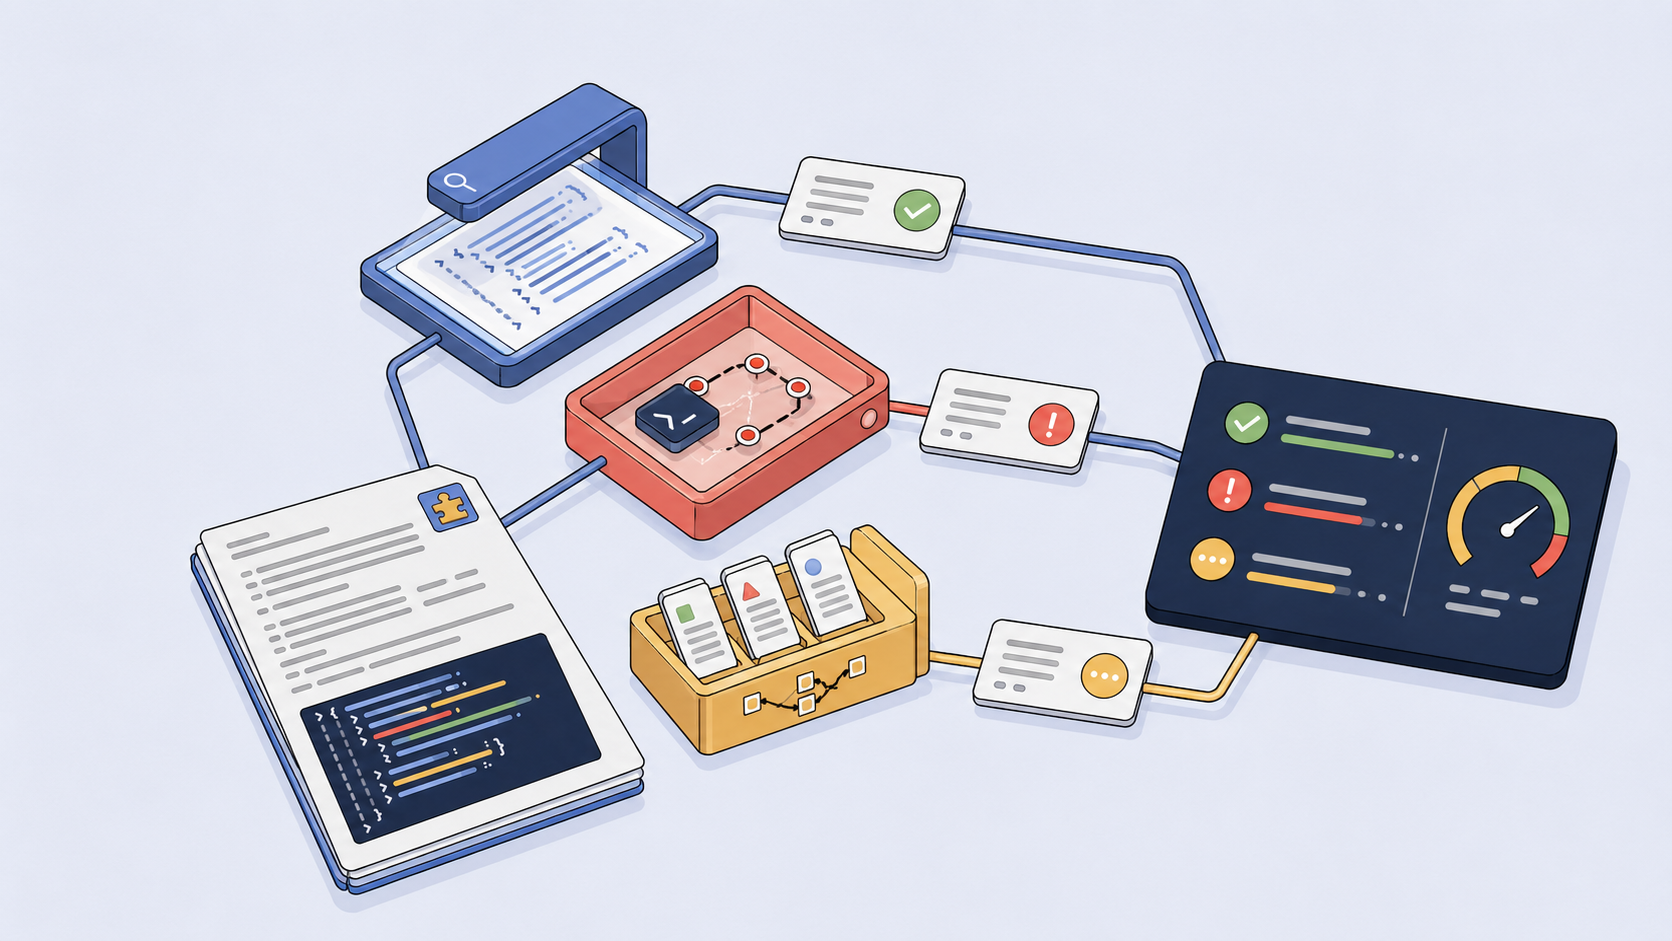
Rules and sandboxes generate evidence. Reasoning over that evidence in context is what tells a security-education example apart from an actual attack.
Not every suspicious pattern deserves equal weight. Here's how a severity-weighted scoring model keeps one high-risk signal from getting diluted by noise.
A scanner that flags everything catches everything, and gets ignored by week two. Noise is the actual failure mode of agent skill security today.
You don't need a six-month rollout to get visibility into the agent skills and AI artifacts running in your organization. Here's a practical starting point.
Third-party marketplaces list well over a million agent skills. Here's what large-scale research says about how many of them are actually dangerous.
Browser, endpoint, source control, upstream registries, and governance. Here's why AI artifact security has to cover all five, not just one.
Your vulnerability management program was built around identifiers that agent skills simply don't have. That gap is bigger than most security teams realize.
A practical checklist for figuring out how exposed your organization actually is to malicious agent skills, and where the gaps usually hide.
A ransomware affiliate ran real intrusions by driving an agentic coding assistant. The agent sat entirely on the attacker's side of the wire, and the same tradecraft works far better one hop inside.
Agent skills are the most visible risk right now, but the same install-to-execution trust gap runs through models, datasets, and MCP servers too.
Not every skill deserves the same scrutiny. A trust tier model gives internal, curated, and marketplace skills the review they actually warrant.
OWASP's MCP Top 10 catalogues the ten most critical risks in Model Context Protocol deployments. What each entry covers, and which ones to fix first.
OWASP published the Agentic Skills Top 10 in August 2026. What each of the ten risks says, the evidence behind them, and where security teams should start.
Static, dynamic, and reasoning-based scanning carry different costs and latency. Here's where each one actually belongs in your delivery pipeline.
Point solutions catch point problems. Defense in depth for the AI supply chain means inspecting the artifact itself at every point it enters your environment.
A walkthrough of a real malicious agent skill from our research dataset, from its innocent-looking description to the socket connection that gave it away.
A score with nothing behind it gets argued with once and ignored after that. Here's what changed when we made every verdict carry the evidence that produced it.
Static rules, sandboxed execution, and reasoning over evidence each catch something the other two miss. None of them is sufficient alone, and our own benchmark shows exactly why.
You probably don't need a new control framework for agent skills. You need to notice that several controls you already run were written as though this category didn't exist.
Static review reads what a skill says it will do. A sandbox shows what it actually does the moment it runs.
Signature and pattern matching are fast, cheap, and necessary. They're also the layer attackers find easiest to route around, and the data backs that up.
The scanning is rarely the bottleneck. Across the reviews and rollouts we sit in on, the same three organisational problems show up long before any tool does.
An MCP server that looks legitimate can still be built to harvest session tokens and tool outputs. Here's what impersonation looks like and what actually stops it.
Some of the riskiest agent skill attacks never touch a binary. They target how the agent reads instructions, not how a program executes.
A malicious skill doesn't need to do damage immediately. It just needs to write itself into a shell profile, cron job, or agent config once, and it survives long after the conversation ends.
Fetching and running a remote script at runtime is a decades-old pattern. In an agent skill, it's one of the fastest paths from install to full compromise.
Base64 strings and eval-like execution aren't inherently malicious, but they're exactly how attackers keep exfiltration logic invisible to a plain-text code review.
The most common malicious agent skill archetype doesn't announce itself. It looks like a benign tool while quietly collecting API keys, tokens, and conversation context.
A shadow feature is a capability built into a skill but left out of its description. It's why a skill can pass review and still do something no one approved.
Agent skills give AI assistants the ability to act, not just talk. That power is what makes them the newest link in your software supply chain, and the least inspected one.
New research and engineering posts when they publish.
We use your email to send The Pit Stop and nothing else.